AI PDF Chat
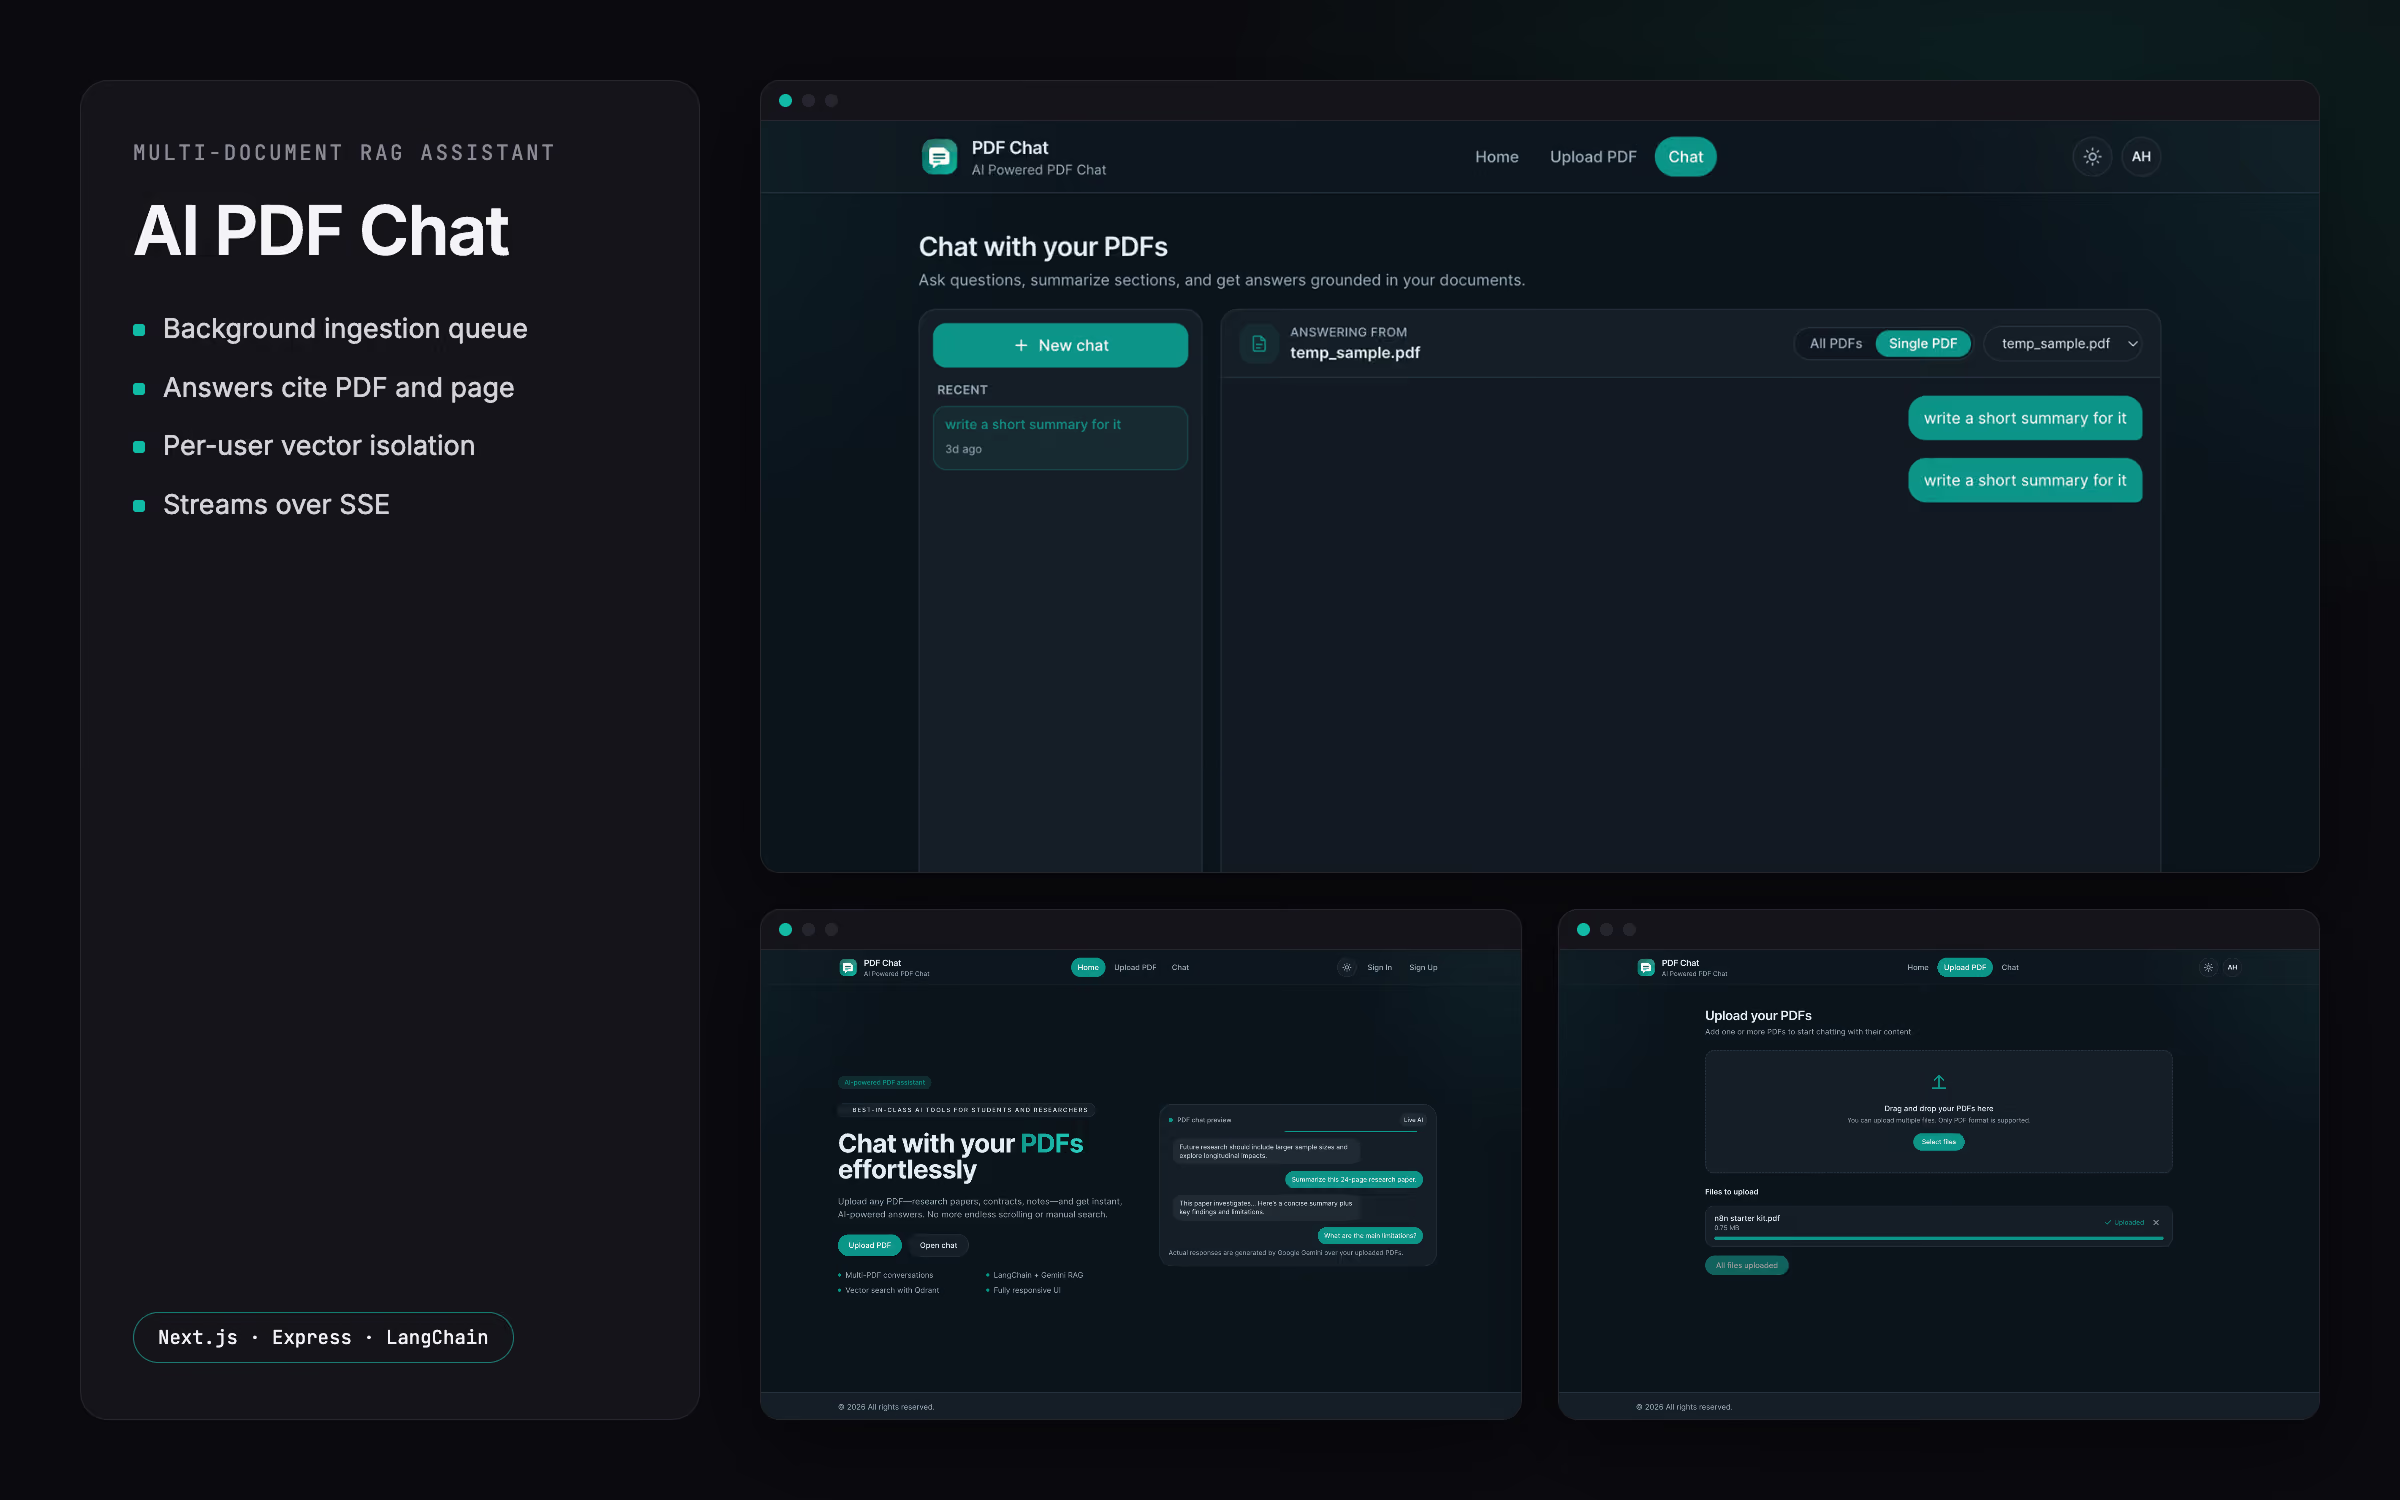
Upload several PDFs and ask questions across all of them or one; every answer cites the PDF and page, and the citation opens the document with the passage highlighted.
- Role
- Full-stack engineer
- Status
- Built
- Next.js
- Express
- LangChain
- Qdrant
- Gemini embeddings
- Groq (Llama)
- Zod
- Docker Compose
The problem
- Context
- A signed-in user uploads several PDFs and asks questions across all of them or inside one. Every answer cites the PDF and page, and the citation opens the document with the passage highlighted.
- Constraints
- The embedding provider's free tier rate-limits hard and, through the library in use, returns empty results instead of an error when it does. Large PDFs produce many chunks, so processing cannot happen inside the upload request. Many users share one vector store, and the model provider had to be swappable.
- What was at stake
- Embedding during the upload would time out on big files. A missed rate limit would quietly fill the index with empty vectors and degrade every answer. A missing user filter would show one person's documents to another, and vectors left behind after a delete would keep surfacing deleted content.
What I built
Background ingestion
Uploads return at once
The upload responds immediately and each file is extracted, chunked and embedded by a background queue, one file at a time, with its status (queued, processing, ready, failed) shown in the app. One file failing never holds up the rest.
Work resumes after a restart
On startup, files that were mid-processing are put back in the queue, so a restart never leaves a document stuck.
A swappable model provider
Chat and embeddings are chosen from configuration, with a hosted provider by default and a local model as an option, so the vendor can change without touching the pipeline.
Reliability under rate limits
Catching the silent rate limit
Empty or short vectors are treated as a hidden rate-limit response and retried with exponential backoff; if it never recovers, the user sees a plain message about the limit. Batches are paced to stay under it in the first place.
Safe to retry, safe to crash
Each re-ingest clears the file's old vectors first, so retries never create duplicates. A file deleted mid-processing is cleaned up instead of resurrected, and a scanned PDF with no text is marked failed with a useful message rather than shown as ready.
Isolation and clean deletes
Every search filtered by user
Searches always filter by the signed-in user, and by the file in single-document mode, on indexed fields, with a relevance threshold so weak matches are not passed to the model.
Ownership checked everywhere
Viewing, deleting and retrying files, and reading chat history, are all scoped to the signed-in user; the raw PDF route replaced an earlier open folder. Sign-in endpoints are rate-limited separately.
Deletes that leave nothing behind
Deleting a PDF removes the file, its record and its vectors, and the conversations that cited only that file, while keeping conversations that drew on other documents too.
Answers you can check
Streamed answers with citations
Answers stream as they are written and are restricted to the retrieved content. Citations are grouped per file and page and carry the best-matching passage, which the viewer highlights; recent turns are kept so follow-up questions make sense.
Tell me what you’re building and where it’s stuck.
I’ll tell you the cleanest path forward, including if it’s “don’t build that.”
Or write tocontact@alihassan.dev